AI Document Indexing: Turning Unstructured Content Into AI Knowledge

Rohit Joshi
Last updated on September 1, 2026
Document indexing turns PDFs, wikis, and internal files into searchable data that a RAG pipeline can retrieve and use.
The process typically moves through five stages: parsing, chunking, embedding, vector storage, and retrieval.
Poor indexing or chunking can break retrieval before the AI sees the question, leading to generic or hallucinated answers instead of responses grounded in your own documents.
AI document indexing is now at the centre of every modern business that relies on automation, AI chatbots, or intelligent search.
It ensures that valuable information in your PDFs, wikis, and internal documents is organised, accessible, and ready to power your AI systems.
Without proper indexing, critical business knowledge often stays hidden and unable to support decision-making, customer queries, or automated workflows.
In this blog, you will find a practical breakdown of how AI document indexing works, why it’s essential for Retrieval-Augmented Generation (RAG), which tools can help, and the steps you can take to build an effective, error-free pipeline for your business.
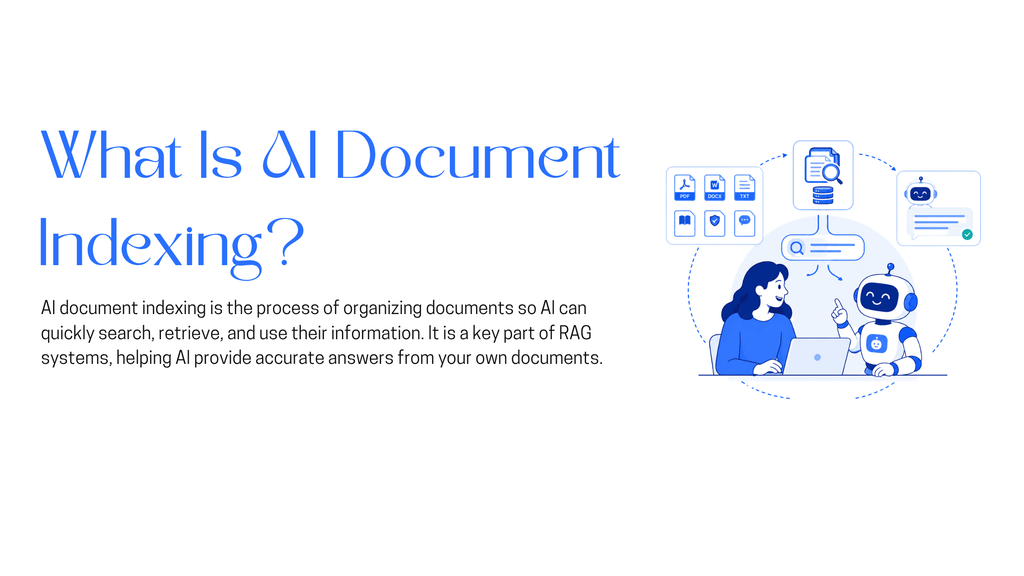
AI document indexing is the process of transforming unorganised files PDFs, onboarding manuals, internal policies, chat logs into structured content that AI models can search, retrieve, and use to generate accurate answers.
This is a most critical partof Retrieval-Augmented Generation (RAG) pipelines, where the language model supplements its internal knowledge with real information from your own documents.
If your files aren’t indexed properly, your AI agents cannot fetch reliable data, leading to generic, sometimes hallucinated/inaccurate answers.
| Concept | Definition |
|---|---|
| Parsing | Extracting plain text from files such as PDFs, documents, and web pages by removing noise like headers, footers, and navigation. |
| Chunking | Splitting documents into smaller, meaningful segments such as paragraphs, sections, or topics to improve retrieval. |
| Embedding | Turning each chunk into a vector, a numerical format that captures meaning and is used for semantic search. |
| Vector DB | A specialised database, such as Qdrant or Weaviate, used to store embeddings and perform similarity searches. |
| Metadata | Extra information attached to each chunk, such as the source file, section, and tags, to improve filtering and context. |
Retrieval-Augmented Generation (RAG) has become the gold standard for building reliable, context-aware AI systems. But even the most advanced language models can only generate accurate responses if they have access to relevant, up-to-date information. This is where AI document indexing makes all the difference.
When you index your files:
Example:
A user asks, “How do I claim travel expenses?”
Your internal policy uses the phrase, “Reimbursement for business-related journeys.”
With semantic indexing, RAG finds the answer even when the query and source don’t match exactly.
For any RAG system, document indexing is essential. It enables the conversion of raw data into vectors so that your AI delivers accurate, context-rich responses efficiently.
AI document indexing follows a repeatable pipeline. Each stage turns raw, unstructured content into something AI systems can retrieve and use in real time. Here’s how it works:
Your source documents can include:
Gather all relevant files, no matter their format or location.
Using the Natural Language Processing:
Clean parsing ensures only meaningful content moves to the next step.
Accurate chunking improves retrieval precision for AI queries.
Embeddings are the foundation for matching user questions to the right content.
Every effective RAG system depends on a solid pipeline. It makes sure your business data stays live, reliable, and ready for AI to deliver smart answers
| Use Case | What Gets Indexed | Who Benefits | AI Advantage |
|---|---|---|---|
| Customer Support Automation | FAQs, policies, troubleshooting guides, and chat logs | Customers and support teams | 24/7 answers, consistent responses, and faster resolutions |
| Internal Knowledge Search | SOPs, HR manuals, wikis, and training documents | Employees across teams | Accurate access to internal knowledge across departments |
| Legal & Compliance Auditing | Contracts, regulatory updates, and audit trails | Legal, compliance, and audit teams | Faster document lookups and better policy traceability |
| Contract & Policy Analysis | Agreements, terms, and policy documents | Legal and procurement teams | Extracts clauses and highlights important obligations |
| Employee Onboarding & Training | Onboarding kits, internal FAQs, and workflow documents | HR teams and new employees | Reduces repetitive questions and provides current information |
| Workflow Automation & Triggers | Project documents, tickets, emails, and forms | Operations, product, and IT teams | Detects required actions and helps automate task assignment |
| Customer Self-Service Portals | Product manuals, troubleshooting steps, and guides | End users and partners | Guides users through solutions and reduces support workload |
| Research & Data Analysis | Technical papers, reports, and datasets | Analysts, R&D, and product teams | Surfaces relevant insights and speeds up research |
AI document indexing enables all these use cases by making your knowledge base instantly accessible, meaningfully searchable, and easy to integrate with AI agents, voice agents, and chatbots.
Good indexing begins with clear, well-structured content. How you prepare your files directly impacts how accurately AI can extract, chunk, and retrieve the right information.
This step is only for developers building there custom AI:
When your documents are well-structured, they’re easier to parse, more accurate to retrieve, and help your AI agents perform better in every use case
AI document indexing converts unstructured files like PDFs, Word documents, and wikis into structured, searchable formats so AI can retrieve and use them efficiently.
Document indexing ensures RAG models can retrieve relevant, up-to-date content from your knowledge base to generate accurate and informed responses.
Preferred formats include Markdown (.md), TXT, DOCX, and clean PDFs. Markdown is ideal because its structure is easy for both humans and AI systems to understand.
Well-structured documents use clear headings, logical sections, short paragraphs, minimal clutter, and useful metadata such as titles, categories, or dates.
A vector database stores document embeddings and enables fast semantic similarity searches, which makes it an important part of many RAG-based document indexing systems.
Yes. Small businesses can use AI indexing to make internal knowledge easier to search, improve employee productivity, and automate customer support using their own business information.
Popular tools include YourGPT, Qdrant, Pinecone, Weaviate, LlamaIndex, LangChain, and Chroma. The right option depends on your scale, technical requirements, and how much of the indexing workflow you want to manage yourself.
Update your document index whenever important source content changes, especially after adding new documents, changing policies, updating product information, or revising internal knowledge.
AI document indexing is no longer just a backend technical process, it is a foundational requirement for any business looking to adopt AI agents based on Retrieval-Augmented Generation (RAG) or build custom AI-driven workflows.
When your documents are well-structured, properly chunked, and indexed, your AI system can access the most relevant and up-to-date information. This ensures responses are context-aware and rooted in real business knowledge.
A strong indexing pipeline helps reduce manual search efforts, accelerates customer support and employee onboarding, and enhances compliance and audit preparedness. It help teams with confidence that every AI-generated response is backed by accurate and current company data.
As more businesses integrate AI into their daily operations, the quality of document indexing becomes directly linked to the reliability and trustworthiness of these systems.
Investing in clean document structure, the right tools, and continuous validation ensures your knowledge base remains ready to answer any question now and as your business scales.
Learn how to judge Shopify AI resolution rates with clear formulas, a worked example, ticket-level checks and practical ways to improve support quality.

TL;DR B2B customer service means supporting multiple people within the same account, including end users, admins, finance or procurement contacts, and executive sponsors, each with a different definition of a resolved ticket. Traditional support bots handle one conversation at a time and often lose account context when requests move between contacts, channels, or teams, forcing […]
TL;DR A vector embedding is a list of numbers that represents meaning, placing similar concepts closer together in a mathematical space. AI chatbots use embeddings to match questions by meaning rather than exact wording, which is a core part of retrieval-augmented generation (RAG). Anthropic recommends Voyage AI for embeddings, while OpenAI, Google, and Cohere provide […]

TL;DR An FAQ chatbot answers repetitive questions by matching user queries with a knowledge base and returning grounded responses using rules, AI retrieval, or both. Modern FAQ chatbots use confidence checks to deliver instant answers for strong matches and fall back to broader retrieval or human handoff when confidence is low. Rule-based bots work well […]
TL;DR Multimodal chatbots let customers share photos, screenshots, documents, video, or audio directly in a conversation, giving AI more context than text alone. YourGPT’s Attachment Capture node in AI Studio can collect these files mid-conversation, while vision-capable AI models can analyze and understand their contents. Key use cases include ecommerce returns, insurance and warranty claims, […]
A customer asks where their order is. A traditional bot pastes a tracking link and calls it done. An agentic system checks the carrier API, sees the shipment stuck at a depot, applies a credit under the delay policy, updates the CRM, and messages the customer before they’ve had time to get annoyed. Same question. […]